How Uber Shows Millions of Driver Locations in Real Time | EP: 4 Behind The Screen
This is the 4th episode of my series Behind The Screen, where I explain how the technology behind everyday products works, in the simplest way I can.
Recently I was reading about how Uber’s backend handles large volumes of real-time location events, and I found the design interesting. This post summarizes what I learned from Uber’s publicly available Engineering Blog articles and adds my own simplified explanation.
Polling
Initially, Uber used a polling-based mechanism where the mobile app was responsible for requesting data. The app requested the server for a new location every few seconds, and if a location update is available, it is sent to the app.
Problems with Polling
- Aggressive polling was required to keep the app responsive, but it caused high resource utilization on the server side.
- Faster battery drain was another issue. The app will keep sending location requests to the server even when there is no new location available.
- App cold-start time also increased. When the Uber app opened, it needed to poll multiple APIs to show the latest state in the UI. This leads to multiple API calls, and the UI won’t render until most critical APIs respond.
- At one point, Uber reported that a large share of requests to its backend were related to location polling. See the linked Uber Engineering article for the original measurement and context.
Introducing RAMEN
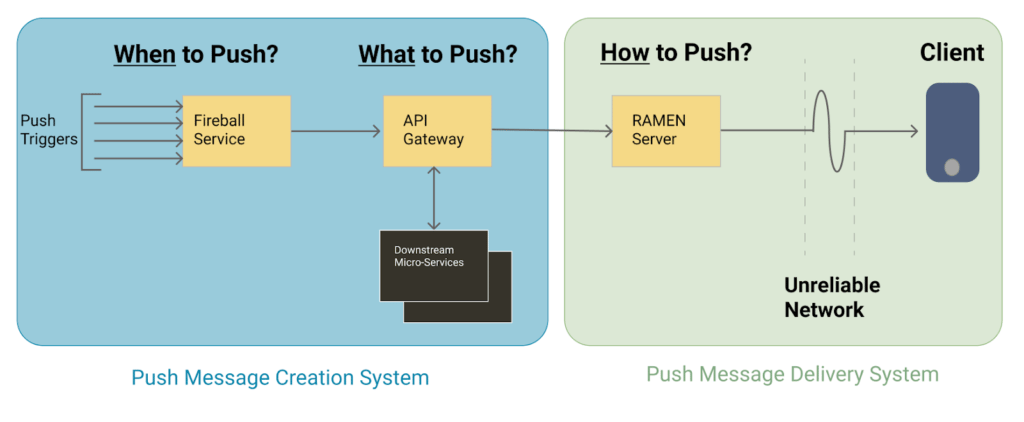
This was the time when Uber realized they needed to revamp this system with a better alternative, and they built RAMEN (Real-time Asynchronous Messaging Network). Instead of the app requesting a new location, Uber used a push-based mechanism. Now the Uber backend decides when a new location update is to be sent to the app.
This raises 3 new questions:
- When to push?
- What to push?
- How to push?
When to Push?
Uber made a microservice and named it Fireball. It was responsible for deciding when to push the data. This service listens to all kinds of events and decides if whether a location update is worth pushing. These events can be:
- User requesting ride.
- Driver accepting ride.
- Change in driver or user location.
- and etc.
As not every little location change needs to be sent to the client, this service makes sure if it is really necessary to send data to the app. Once this service decides that a push should happen, it sends the relevant information to the API Gateway.
What to Push?
The Fireball microservice provides a small amount of information. The API Gateway adds the data required for delivery This can include user locale, OS, app version and other user-related attributes. All this data will then be forwarded to RAMEN.
How to Push?
Once RAMEN receives this data, its responsibility is to deliver the update to the app. RAMEN is a technology that is originally built on top of the TCP protocol. For the application protocol, Uber considered HTTP long polling, WebSockets, and Server-Sent Events (SSE). They chose Server-Sent Events after considering factors such as security, mobile SDK support, and binary size.
SSE is a server-to-client event stream, so the server sends events to the client over the SSE connection. The client can still make separate HTTP requests when it needs to send information back. But Uber needed to guarantee at least one delivery for the message. This required the mobile app to acknowledge delivery. This is how it was solved.
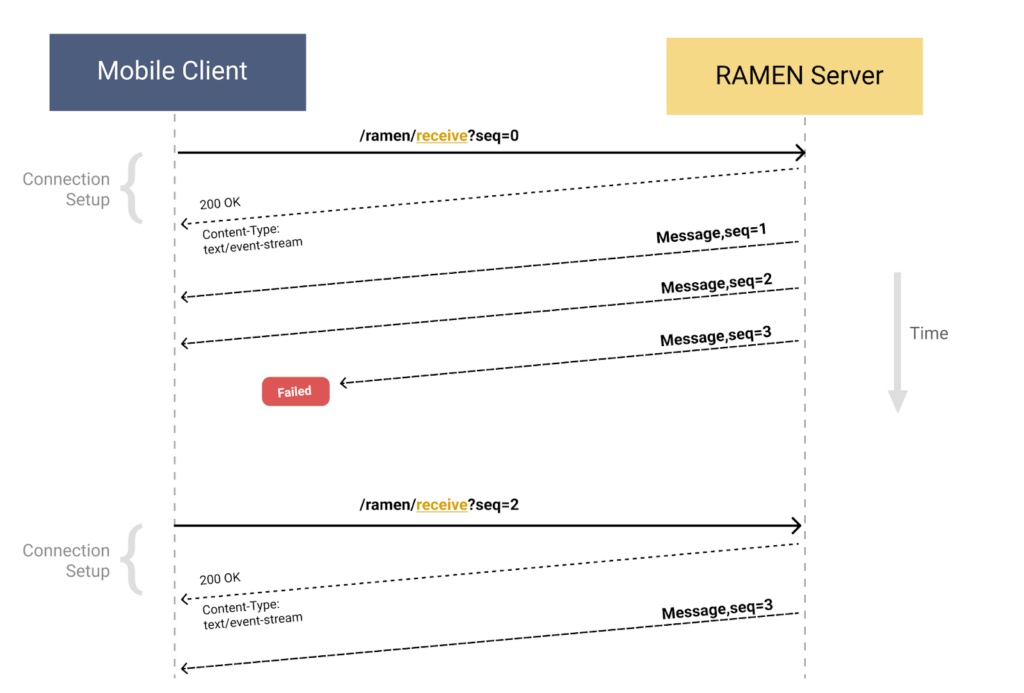
- The client starts the connection by sending an HTTP request to /ramen/receive?seq=0 with a sequence number of 0.
- The server responds with HTTP 200 and ‘Content-Type: text/event-stream’ for maintaining the SSE connection.
- The server will then send all the messages.
- TCP itself does not close a connection merely because an application-level message is missing. In the RAMEN design described by Uber, the application used sequence numbers and connection state to detect gaps or failures and request the missing data again.
- Next time the client is expected to send an HTTP request to /ramen/receive? seq=2 This tells the server to send messages again from sequence 3.
- To check if the connection is alive, the server sends a single-byte-sized heartbeat every 4 seconds.
- If no heartbeat or message is received for up to 7 seconds, the connection is assumed broken and another connection is established.
- Whenever a client sends a request to /ramen/receive with a higher sequence number than 0, it tells the server to flush all older messages.
- But in a good network, a user may remain connected for several minutes, which can accumulate older messages. To solve this issue the app would call /ramen/ack?seq=N every 30 seconds regardless of the connection quality.
Next Gen Push Platform (gRPC)
The above implementation was the initial version of RAMEN that utilized Server-Sent Events and a sequencing mechanism for communication. Later, Uber upgraded RAMEN to use gRPC instead of SSE.
SSE solved issues with HTTP polling, but later it also created some issues. In order to tackle those issues, Uber decided to shift RAMEN to gRPC.
Issues with SSE
- Reliability Issues: In the older design, the delivery state could remain unknown for a period of time because the client acknowledgement/sequence state was handled separately. Uber wanted a more immediate bidirectional mechanism.
- Double Connections: Uber needed to manage 2 connections. One connection for SSE events and another for sequencing.
- Binary Data: SSE is a text-based event-stream format. JSON can be carried inside SSE, but binary data would need an encoding such as base64 or a separate transport, which can add overhead.
Solution
Uber shifted the older SSE implementation of RAMEN to gRPC. gRPC provides bidirectional streaming, allowing the mobile app and server to exchange messages over a single RPC connection. Also gRPC uses Protocol Buffers instead of JSON. Protocol Buffers are a compact binary serialization format and can be more efficient than JSON in many workloads, although the actual performance depends on the data and implementation.
Results
- Real-time acknowledgment was achieved.
- gRPC Connect Latency (p95) was improved by 45%.
- Push success rate improved by 1–2%.
This article is a simplified summary of Uber’s published engineering work, not an independent description of Uber’s private implementation. The design and measurements below are based on the public sources linked here.
If you want to read more in depth, check the following links: